Automation · NLP · Integrations
AI invoice and document processing: a practical playbook
How to automate invoice and document processing with OCR and LLM extraction: schemas, validation, PO matching, confidence-based review and ERP push.
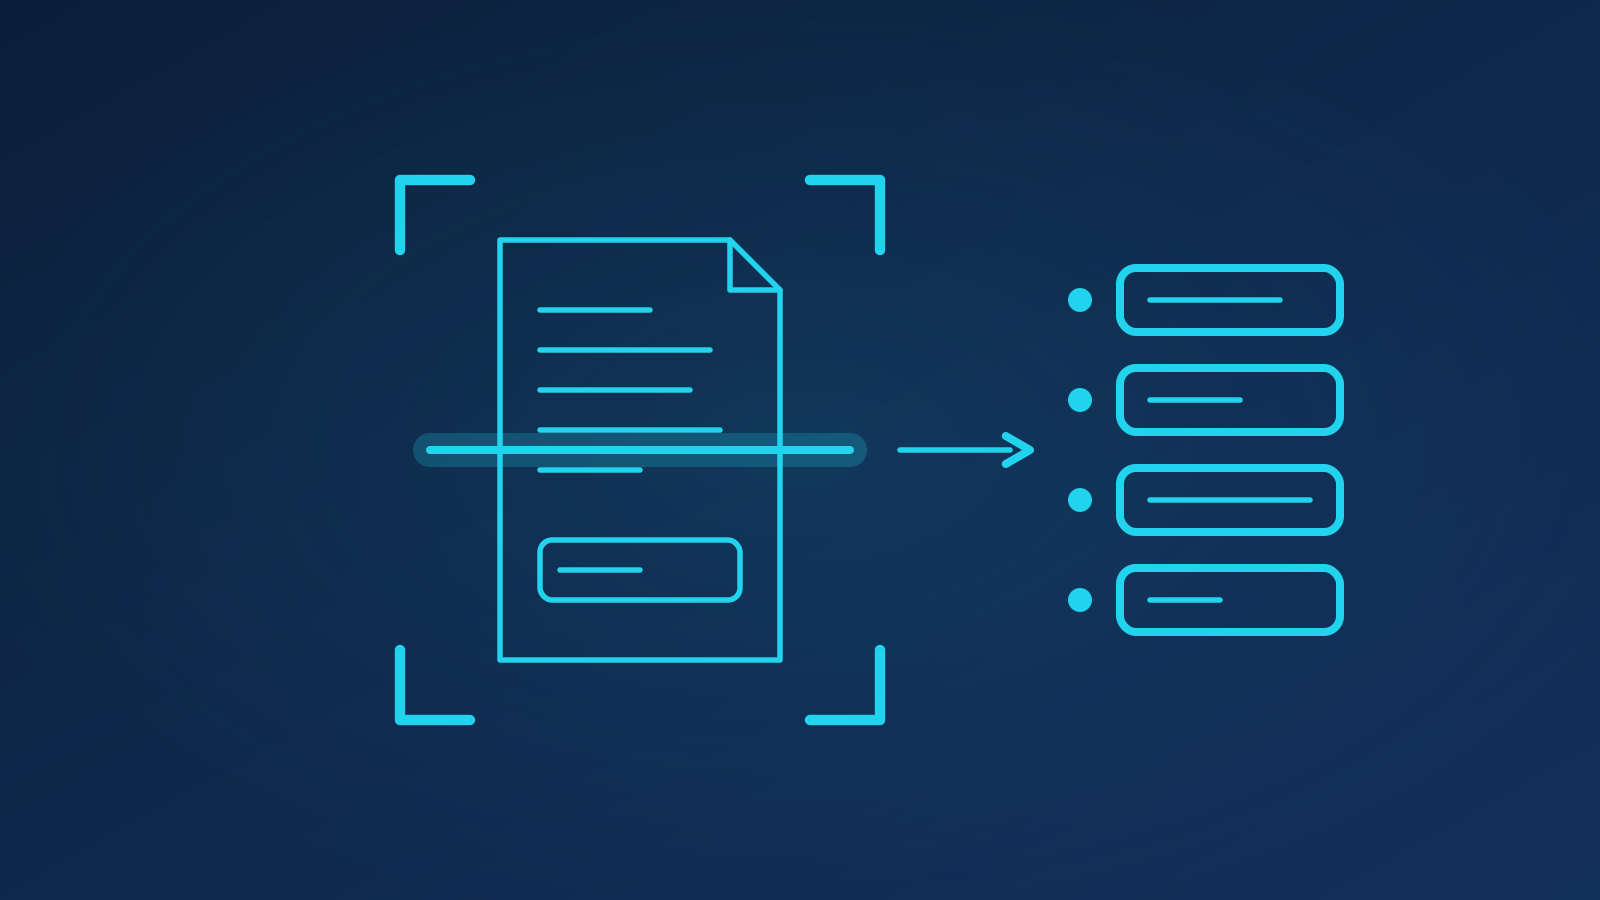
AI invoice processing turns PDFs, scans and email attachments into structured, validated records in your accounting or ERP system with a person checking only the uncertain cases. The reliable version is a pipeline, not a model: capture from every intake channel, OCR plus a language model to extract fields into a fixed schema, deterministic validation, matching to purchase orders, a review queue ordered by confidence, and a push to the system of record. Done well, most invoices flow straight through and finance staff spend their time on exceptions.
TL;DR
- Define the output schema and validation rules before choosing any model.
- Combine OCR with an LLM: OCR reads the pixels, the LLM maps messy layouts to your fields.
- Route by confidence: auto-post the confident cases, queue the rest for a human, and learn from every correction.
- Match to POs and receipts with tolerances, and treat exceptions as a workflow, not a failure.
- Measure field-level accuracy and straight-through rate on a labelled set, and roll out one supplier segment at a time.
Where do documents come in, and what does the pipeline look like?
Invoices arrive by email, supplier portals, scanned post, EDI and occasionally phone photographs. The first job is a single intake (a watched mailbox, a drop folder for scans, an upload endpoint) where every document gets an ID, a source, a timestamp and a stored original before anything else happens.
From there the stages are stable regardless of vendor or model:
- Classify: invoice, credit note, statement, remittance, receipt or something else. Misrouted documents are the quietest source of errors.
- Extract: header fields (supplier, invoice number, dates, currency, totals, tax) and line items into a schema.
- Validate: arithmetic, formats, master-data lookups.
- Match: to purchase orders and goods receipts.
- Route: auto-approve, queue for review or reject to the supplier.
- Post: to the ERP or accounting system, with the original attached and an audit trail.
How do OCR and LLM extraction work together?
OCR engines are excellent at turning pixels into text with coordinates and poor at knowing which text is the invoice number on an unseen layout. Language models are the reverse: given OCR text with layout hints they can identify fields on an unfamiliar template, but should never be trusted to read a blurred digit. Use both.
The output must be a strict schema (JSON with typed fields, enumerations for currency and document type, line items as an array), and the model should be asked to fill it, not to write prose. Anything absent is null, never guessed. Ask for the source text or bounding box behind each field so a reviewer can click through to the original.
Different documents call for different approaches:
| Document type | Layout variability | Recommended approach | Human review |
|---|---|---|---|
| Supplier invoices, many templates | High | OCR + LLM to schema | Confidence-routed |
| Own-format forms (expense claims, timesheets) | Low | Template/zonal OCR, LLM fallback | Spot checks |
| Contracts and long PDFs | High, long | Section-aware LLM extraction, RAG for clauses | Always for key terms |
| Receipts and photos | High, poor image quality | OCR with preprocessing + LLM | Low-value auto-approve |
| Bank statements, remittances | Tabular | Table extraction + rules | Reconciliation exceptions |
Which validation rules catch the most errors?
Validation is deterministic and cheap, and it catches most of what a model gets wrong. The rules we install first:
- Arithmetic: line totals sum to the subtotal; subtotal plus tax equals the total; tax rate is plausible for the jurisdiction.
- Formats: dates parse and are in a sensible window; IBANs, VAT numbers and invoice numbers match the expected patterns.
- Master data: supplier resolves to a vendor record; bank details match the record on file (a mismatch is a fraud flag, not a typo).
- Duplicates: same supplier, number and amount already posted.
- Business rules: currency matches the vendor, payment terms are within policy.
Each failed rule lowers a document's confidence and adds a reason a reviewer can see. Confidence itself is a blend: the model's own field scores, OCR character confidence and rule outcomes, calibrated against your labelled set rather than taken at face value.
How do you match to purchase orders and handle exceptions?
Two-way matching compares invoice lines to PO lines on item, quantity and price; three-way matching adds the goods receipt. Real invoices rarely match perfectly, so set tolerances and let anything within them pass. Partial deliveries, invoices covering several POs and freight lines absent from the PO are the usual mismatches; handle each with an explicit rule rather than a person's memory.
The review queue is a product in its own right. Order it by confidence and by amount, show the extracted fields beside the original with the offending field highlighted, and let the reviewer correct in place with a keystroke. Every correction is logged and becomes training and evaluation data. Exceptions that cannot be resolved internally, such as a missing PO number or an unknown supplier, go back to the supplier through a templated email with the specific problem stated.
Once approved, the record is posted to the ERP or accounting system (SAP, Dynamics, NetSuite, Xero, QuickBooks) through its API, with the original document attached and the extraction confidence and reviewer stored on the record. This is integration work with the usual disciplines: idempotent posts, retries, reconciliation reports.
How do you measure accuracy and roll it out?
Measure at the field level, not the document level. Build a labelled set of a few hundred documents that reflects your real supplier mix, and track:
- Field accuracy: exact match per field, with totals and supplier weighted more heavily.
- Straight-through rate: share of documents posted without a human touch.
- Review precision: how often the queue contains something a human actually needed to fix. A queue full of correct documents means the threshold is too tight.
- Cycle time: receipt to posting.
- Cost per document: model, OCR and review time.
Roll out in phases. Start with one high-volume supplier segment with stable templates, run in shadow mode for a few weeks so every document still gets human review, and compare. Raise the auto-post threshold as the numbers earn it. As an illustration, a team processing a few thousand invoices a month might target a majority straight-through within a quarter and grow from there.
The same automation approach extends to credit notes, expense claims, delivery notes and contracts, using the NLP building blocks that make extraction reliable. If your team is spending its days retyping invoices, talk to us about where to start.
Key takeaways
- Fix the schema and validation rules first; they do more for accuracy than the choice of model.
- Pair OCR with an LLM and demand structured output with nulls, never guesses.
- Route by calibrated confidence and treat the review queue as a product that feeds back into evaluation.
- Match with tolerances and encode the common mismatch cases as rules.
- Measure field-level accuracy and straight-through rate on labelled data, and roll out one segment at a time.
FAQ
Do we still need OCR if we are using a language model?
Yes, in most cases. Vision-capable models can read a page directly, but dedicated OCR still gives better character-level accuracy on scans, stamps and small print, and it returns coordinates that let a reviewer see exactly where a value came from. The practical pattern is OCR for reading, the language model for understanding, and the two confidence signals combined when deciding whether a document needs a human.
What accuracy should we expect, and how do we know it is real?
Only a labelled set from your own suppliers can answer that. Measure per field, because a document with one wrong total is a costly document even if nineteen other fields are correct. Track accuracy separately for high-value fields, and re-run the evaluation whenever templates, prompts or models change. Numbers quoted by vendors on generic benchmarks tell you very little about your particular mix of scans and layouts.
How do we keep sensitive financial data safe in the pipeline?
Keep documents in your own storage with access controls and retention rules, send only what is needed to a model endpoint, and prefer providers or self-hosted models with contractual guarantees on data use. Log every access and every automated post for audit. Treat bank-detail changes as high-risk events that always require a human, since invoice fraud typically works by changing the payee rather than the amount.
Written by
Ali Raza · Full Stack Engineer
Turns models into products: APIs, integrations, dashboards and the deployment pipelines that keep them running.
About the team →Related services
Ready to chart your AI course?
A free 30-minute consultation: we listen, ask hard questions and tell you honestly where AI will and won't help.